
Painting flowers with code
As this blog post shows, you can train a model to create watercolour sketches of flowers using p5.brush, and use a judge to do pairwise comparisons against a reference pool of images for the reward function.
In this tutorial, we’ll use Modal Dojo to train Qwen3.5-4B and use HuggingEnvs/watercolour-reference-pool as the reference pool. During each rollout, sketches are rendered to PNGs in a Modal Sandbox and Qwen3.6-27B compares each against the reference image pool.
Run this example:
uv run --python 3.12 --script 06_gpu_and_ml/paint_flowers/paint_flowers.pySet up
This script requires some dependencies to be installed locally. We include the
following inline script metadata so that
tools like uv can automatically install these
dependencies.
# /// script
# requires-python = ">=3.12"
# dependencies = [
#   "modal-dojo @ git+https://github.com/modal-projects/modal-dojo@main",
#   "pillow",
# ]
# ///
import argparse
import asyncio
import base64
import itertools
import random
from helpers import (
RENDER_JS,
SYSTEM_PROMPT,
extract_sketch,
launch_hpsv3,
overlay_flower_image,
renderer_image,
score_png,
skip_infra_rewards,
)
from modal_dojo import (
DatasetConfig,
Endpoint,
Qwen3_5_4B,
Qwen3_5_4B_Recipe,
Qwen3_6_27B,
Sandbox,
TrainConfig,
)
from modal_dojo.common.sample_extraction import IMAGE_SAMPLE_LIMIT_ENVSelect a base model
Modal Dojo comes with preset model classes that handle weight downloading, response parsing, and architecture details for you behind the scenes.
base_model = Qwen3_5_4B()Get the dataset
Using the present species and palette colors in the reference pool, we create a dataset of prompts to train our model on.
SPECIES = ["hibiscus"]
PALETTES = [
    "peach",
    "crimson",
    "butter",
    "lilac",
    "coral",
    "indigo",
    "blush",
    "amber",
]

USER_TEMPLATE = (
    "Paint a {palette} {species} in watercolour: one bloom, seen from the "
    "front, with a stem and leaves, on coloured paper."
)


def build_prompts(combos: list[tuple[str, str]], n: int) -> list[dict[str, str]]:
    rows = []
    for species, palette in itertools.islice(itertools.cycle(combos), n):
        rows.append({"prompt": USER_TEMPLATE.format(species=species, palette=palette)})
    return rows


class FlowerPromptDataset(DatasetConfig):
    def __init__(self, prompts: list[dict[str, str]]):
        self.prompts = prompts

    def input_key(self) -> str:
        return "messages"

    def label_key(self) -> str:
        return "label"

    def rows(self):
        return [
            {
                "messages": [
                    {"role": "system", "content": SYSTEM_PROMPT},
                    {"role": "user", "content": r["prompt"]},
                ],
                "label": r["prompt"],
            }
            for r in self.prompts
        ]


N_TRAIN = 224
N_EVAL = 8

combos = list(itertools.product(SPECIES, PALETTES))
random.Random(7).shuffle(combos)
train_dataset = FlowerPromptDataset(build_prompts(combos, N_TRAIN))
eval_dataset = FlowerPromptDataset(build_prompts(combos, N_EVAL))
Create a reward function
The reward function renders each sketch in a Modal Sandbox and uses an LLM judge to do pairwise comparisons. We serve the judge as an Endpoint.
def deploy_judge():
    print("deploying judges...")
    judge = Endpoint.launch(
        Qwen3_6_27B(),
        unauthenticated=True,
        recreate_if_existing=True,
    )
    launch_hpsv3()
    judge.wait_until_ready(timeout=30 * 60)
    return judge


def render_in_sandbox(code: str) -> tuple[bytes | None, dict]:
    try:
        with Sandbox(
            image=renderer_image(),
            workdir="/render",
            timeout=300,
            cpu=1.0,
            memory=2048,
            block_network=True,
            app_name="dojo-flower-render",
        ) as sandbox:
            sandbox.write("/render/render.js", RENDER_JS)
            sandbox.write("/render/sketch.js", code)
            result = sandbox.run(
                "node", "/render/render.js", "/render/sketch.js", timeout=180
            )
        out, err = result.stdout, result.stderr
        if "PNGB64:" in out:
            png = base64.b64decode(out.split("PNGB64:", 1)[1].strip())
            return png, {"render": "ok"}
        kind = "fail" if "SKETCH_ERROR:" in err else "unavailable"
        return None, {"render": kind, "stderr": err[-400:]}
    except Exception as e:
        return None, {
            "render": "unavailable",
            "stderr": f"{type(e).__name__}: {e}"[-400:],
        }


def make_flower_rm(judge):
    async def flower_rm(args, sample, **kwargs) -> float | None:
        code = extract_sketch(sample.response, base_model.parse_response)
        if code is None:
            reward, meta, png = 0.0, {"gate": "no valid sketch"}, None
        else:
            png, render_meta = await asyncio.to_thread(render_in_sandbox, code)
            reward, meta, png = await asyncio.to_thread(
                score_png, png, code, judge, render_meta
            )
        metadata = {**(getattr(sample, "metadata", None) or {}), **meta}
        if png is not None:
            metadata["image"] = png
        sample.metadata = metadata
        if reward is None:
            sample.remove_sample = True
        return reward

    return flower_rm
Start training
After that, it’s simple to start training! For more information on deploying the checkpoints and running evals, see this guide.
ROLLOUT_BATCH_SIZE = 8
N_SAMPLES_PER_PROMPT = 8


def build_config(judge, num_rollout):
    return TrainConfig(
        model=base_model,
        dataset=train_dataset,
        eval_dataset=eval_dataset,
        recipe=Qwen3_5_4B_Recipe(
            custom_rm_function=make_flower_rm(judge),
            custom_reward_post_process_function=skip_infra_rewards,
            num_rollout=num_rollout,
            rollout_batch_size=ROLLOUT_BATCH_SIZE,
            global_batch_size=ROLLOUT_BATCH_SIZE,
            n_samples_per_prompt=N_SAMPLES_PER_PROMPT,
            save_interval=50,
            apply_chat_template_kwargs='{"enable_thinking": false}',
            image_overlay=lambda image: overlay_flower_image(image).env(
                {IMAGE_SAMPLE_LIMIT_ENV: str(ROLLOUT_BATCH_SIZE * N_SAMPLES_PER_PROMPT)}
            ),
        ),
    )


if __name__ == "__main__":
    parser = argparse.ArgumentParser()
    parser.add_argument(
        "--num_rollouts", type=int, default=100, help="Number of rollouts to run"
    )
    args = parser.parse_args()

    judge = deploy_judge()
    config = build_config(judge, num_rollout=args.num_rollouts)
    run = config.launch()
    print(f"run id: {run.training_run_id}")
Monitor the run
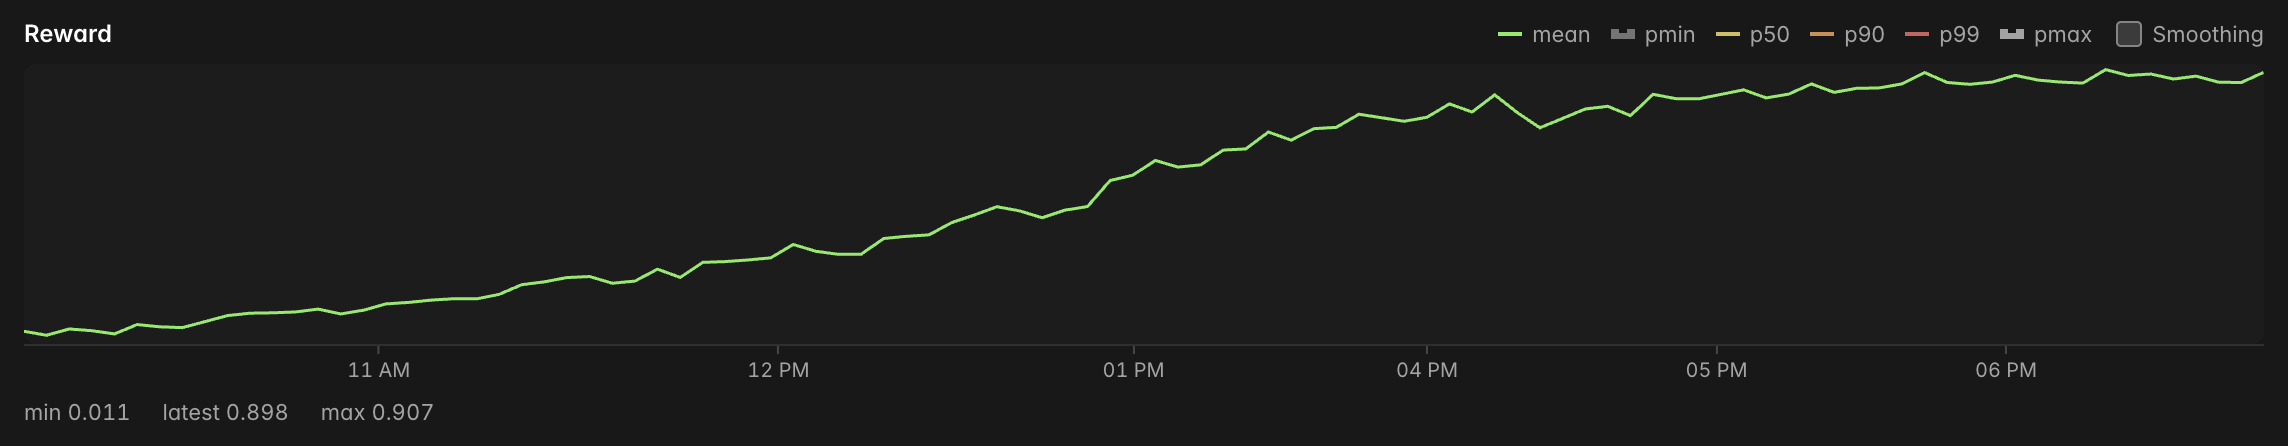
To track the run’s progress, you can deploy the native dashboard with:
modal-dojo setupIt gives you a live view of reward curves, score/advantage distributions, traces, and step timing. Note that it’s just a Modal App, so it tracks runs scoped to your Environment. In addition, it logs all metrics emitted by the library.