Model APIs
Create your own frontier
Access the latest in open weight intelligence, optimized for performant inference on any workload.
Open intelligence served on production-grade infra
Run open weight models on optimized endpoints with OpenAI-compatible APIs. Backed by the latest inference serving techniques and a multi-cloud compute plane.


Deploy the latest open weight models the day they launch.
Get startedDeploy frontier models
Pay only for the tokens you use, with intelligent routing to maximize KV cache hits and minimize cost.
Production-grade quality
Evals verified by leading model labs for production serving performance.
Multi-cloud reliability
Served from Modal's multi-cloud, autoscaling compute pool for consistent reliability.
Deploy the latest open weight models the day they launch.
Get startedDeploy frontier models
Pay only for the tokens you use, with intelligent routing to maximize KV cache hits and minimize cost.
Production-grade quality
Evals verified by leading model labs for production serving performance.
Multi-cloud reliability
Served from Modal's multi-cloud, autoscaling compute pool for consistent reliability.
Production-grade performance
Kernels tuned for inference
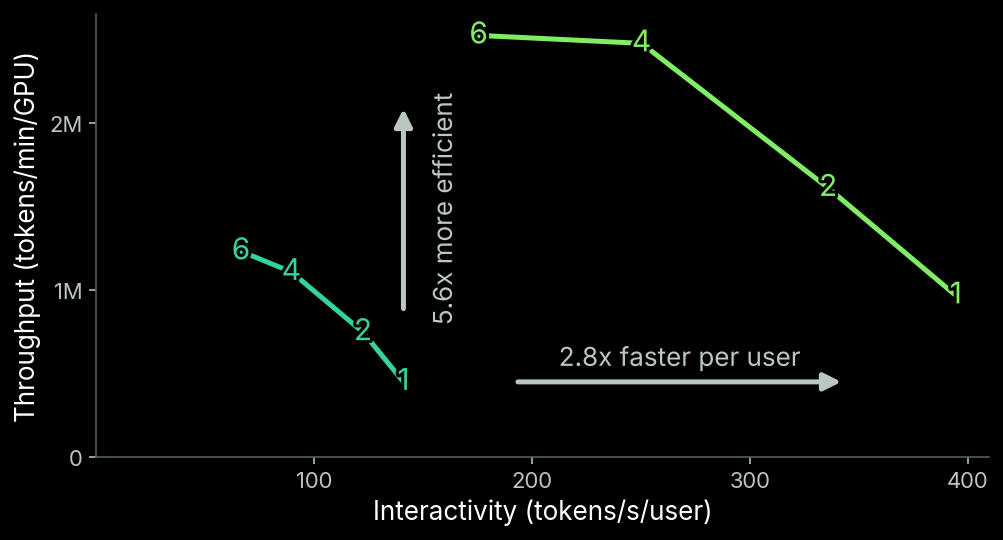
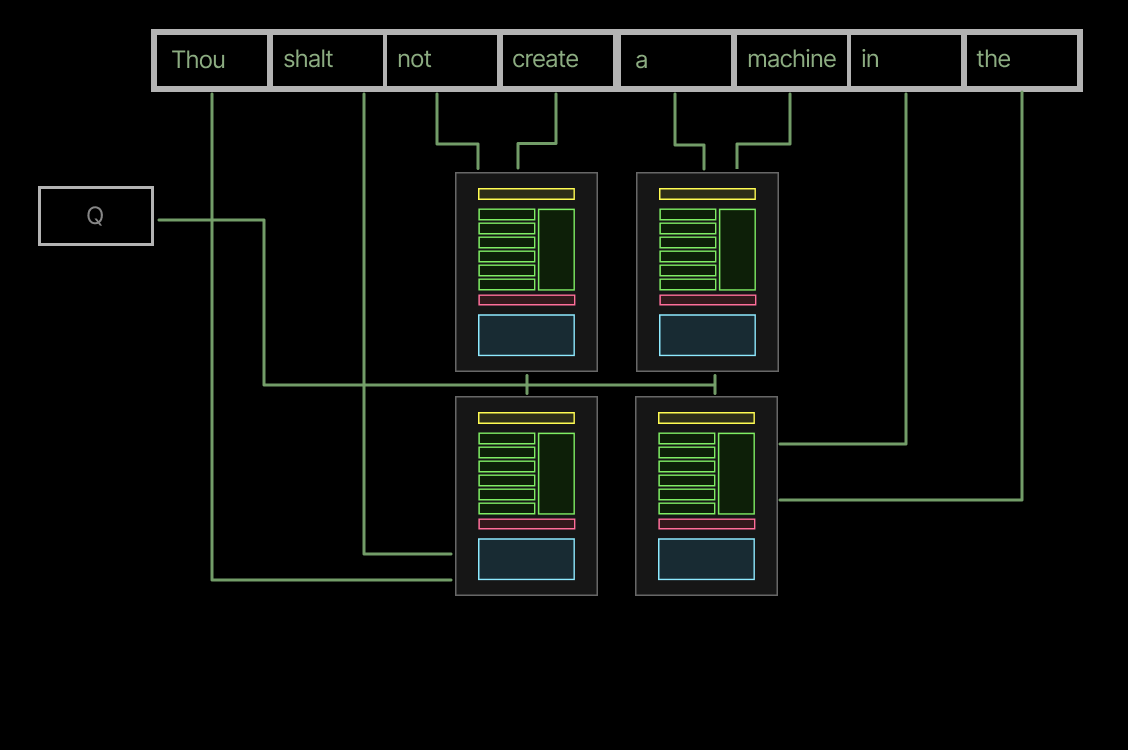
Our FlashAttention-4 contributions add KV parallelism and support irregular memory access for decode-heavy workloads.
KV cache-aware routing
Intelligent, stateful routing keeps cache hit rate high for long-running workloads, reducing time to first token and serving costs.
Balance work across replicas
Load-aware placement splits concurrent sessions across replicas and sends new sessions to new capacity during scale-ups.
Designed for security and data privacy
Zero Data Retention (ZDR) by default
Zero data retention means we never store prompts or responses from Model APIs.
No data use
Your data is never used to train models. Inference runs entirely on Modal, so nothing is shared with model labs.
Encrypted in transit
All traffic to and from Model APIs is encrypted in transit with TLS
Built on the core of inference research
Optimizing the FlashAttention-4 kernel
Key/value parallelism and irregular memory access make the kernel faster for decode-heavy inference.

Speculation is all you need
How we train custom speculators for state-of-the-art inference performance.